Fit × intent × timing: an account scoring model sales actually trusts
Most lead scores get built, presented once and then quietly ignored by sales, because nobody can explain why a lead has 87 points. An account scoring model that separates fit, intent and timing, lets old signals decay and explains every number gives sales a reason to open that CRM field at all.
 ByMario Maier
Published 18 min read
Contents
- Why sales ignores your lead score
- What an account scoring model does differently
- Which buying signals count and which are just noise
- How to weight it: multiply, don't add
- How an agent computes and explains the score
- Worked example: a logistics software vendor with 40 target accounts
- What agents do and what humans decide
- Which metrics show your scoring works?
- Common account scoring mistakes
- Your first four weeks
Why sales ignores your lead score
Almost every B2B team has built a lead scoring model at some point. Ten points for the whitepaper download, five for the newsletter click, twenty for the right job title. It gets presented at the kick-off and configured in HubSpot or Salesforce, and three months later nobody looks at it. A finer points system won't change much. What I build instead is an account scoring model that rates fit, intent and timing separately and explains every number it produces.
These projects rarely fail on the tech. They fail on trust. A score that ranks a student with three downloads above the CEO who visited the pricing page once costs sales a wasted call. After the second one, nobody picks up the phone just because a score is high, and from then on the score is a CRM field nobody reads.
On top of that, almost every points model I come across has the same structural flaws. It counts activity and mistakes it for buying readiness, so whoever clicks most wins, whether they can buy or are just researching. It scores people, even though companies buy. At high contract values a buying group decides (Gartner describes typical B2B purchases as involving six to ten stakeholders), and a per-contact score only ever sees a slice of that. It also never forgets: points from last spring count as much as yesterday's visit, so the score only goes up and never comes down.
Below is how I set up a score that sales will use, from the signals, the weighting and decay and the thresholds through to how an agent computes and explains the score and where a human decides.
What an account scoring model does differently
An account scoring model estimates how likely it is that an account wants to solve a problem you can solve right now. To get there, it answers three questions, each on its own:
- Fit: does the account match your ICP? Industry, size, region, tech stack, business model, plus the exclusion criteria, which matter just as much.
- Intent: is the account engaging with your topic right now? Repeat visits to pricing and comparison pages, replies, webinar attendance, topic signals from third-party providers.
- Timing: is there a trigger that makes the topic urgent right now? A new executive, a funding round, job postings that point to a project, a system change.
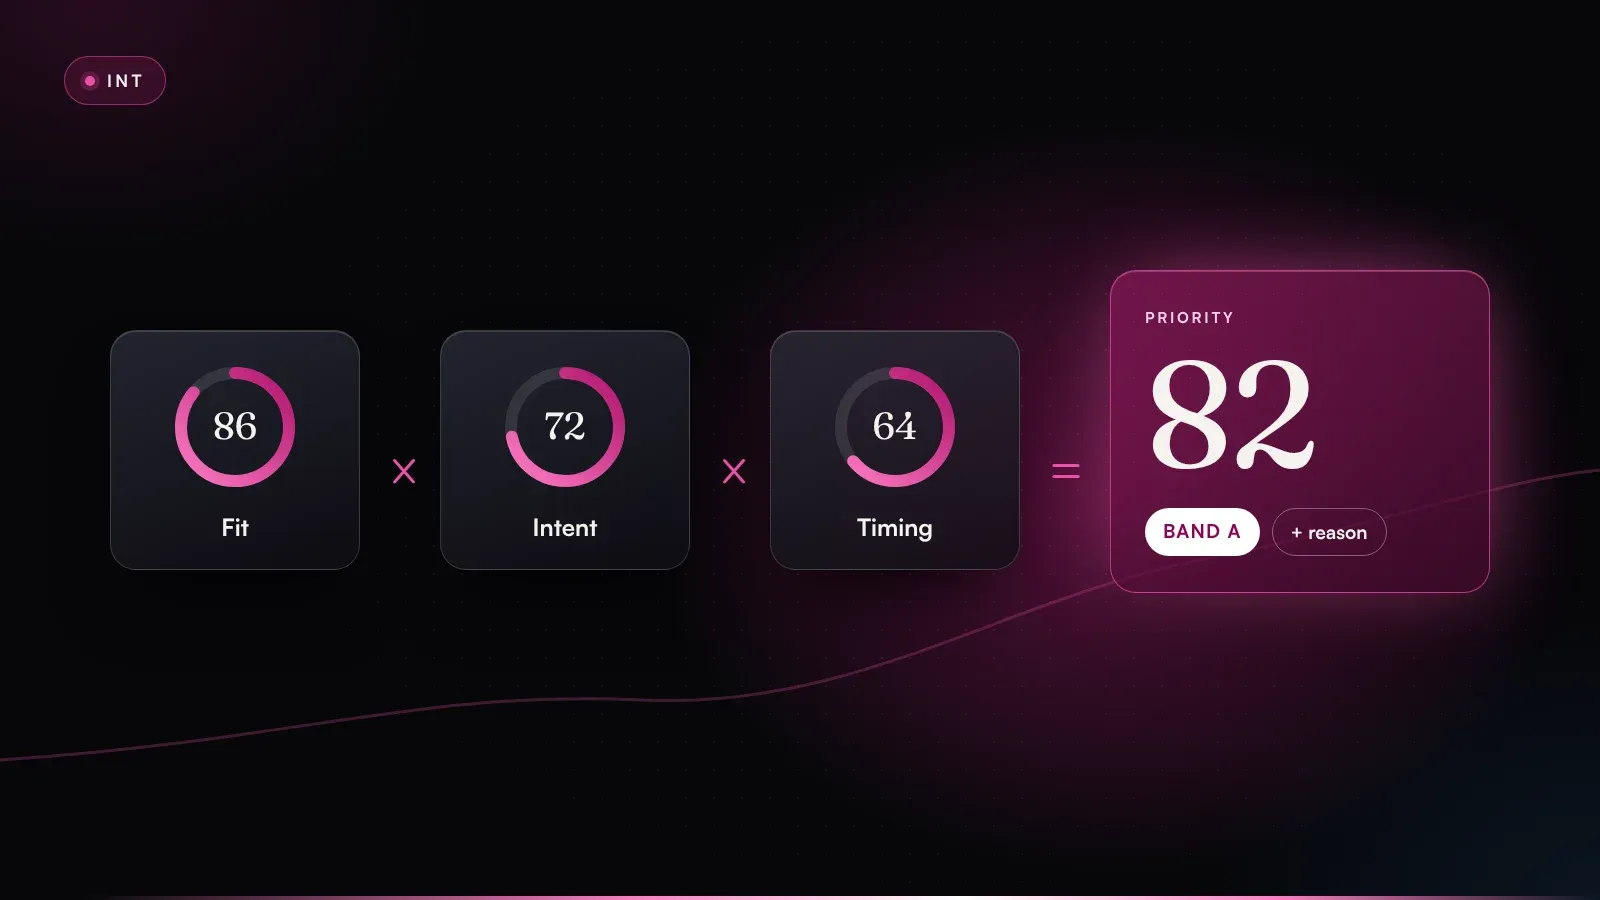
Fit, intent and timing are multiplied, not added – if one dimension is missing, the priority drops sharply.
Keeping them apart is what makes the score readable. When sales sees “fit 85, intent 71, timing 68”, everyone knows instantly where the strength lies and what's missing. A single 74 tells you none of that.
The second difference is the level. Intent scoring works on accounts, so signals from different people at the same company add up. Two people from operations and IT reading the pricing page in the same week tell me a lot more than one person opening it five times.
| Criterion | Classic lead scoring | Fit × intent × timing |
|---|---|---|
| Unit | Individual person | Account with its buying group |
| Math | Add up points | Multiply dimensions |
| Time | Points last forever | Signals decay with a half-life |
| Output | One number | Three values, a priority and the reasoning |
| What a high score triggers | Automatic hand-over to sales | A proposal with human go |
| Maintenance | Built once, rarely changed | Weekly review, rules in the knowledge base |
Which buying signals count and which are just noise
Not every signal is worth the same. My rule of thumb is that the closer a signal sits to a buying decision and the more effort it costs the account, the more it counts. A newsletter click takes a second. Three visits to the pricing page in one week, spread across two people, take attention, and nobody gives that away for nothing.
Fit works a little differently. You need criteria for it more than signals, and those come from your win/loss analysis. They belong in the “ICP & segments” module of the RevPrime® knowledge base: which industries and sizes do you win disproportionately often? Which tech stack makes adoption easy or hard? Whom do you deliberately exclude, such as customers with an open deal, competitors, partners or countries you don't serve?
For intent and timing, I work with a signal catalog. The table below is a typical starting point for a B2B SaaS company with its own sales team. Treat the weights and half-lives as starting values you'll calibrate (they're not laws of nature).
| Signal | Dimension | Starting weight | Half-life | Typical source |
|---|---|---|---|---|
| Reply to an email, LinkedIn message or event conversation | Intent | 30 | 21 days | CRM, inbox |
| Several pricing page visits within 14 days | Intent | 25 | 7 days | Website with company identification |
| Comparison or alternatives page read | Intent | 18 | 10 days | Website |
| Two or more people from the account active | Intent | up to 15 | 14 days | Website, CRM |
| Live attendance at a webinar or workshop | Intent | 12 | 21 days | Webinar tool |
| Topic surge in third-party intent | Intent | 10 | 14 days | e.g. Bombora, G2 |
| Case study from their own industry read | Intent | 6 | 14 days | Website |
| Blog visit, newsletter click | Intent | 0–2 | 7 days | Website, email tool |
| New executive in a target role | Timing | high | 90 days | LinkedIn, press releases |
| Job postings related to your problem | Timing | medium | 60 days | Careers page, job boards |
| Funding, acquisition, expansion | Timing | medium | 120 days | News, company registers |
| Change in the tech stack | Timing | medium | 90 days | Technographic data |
A few things stand out once you build a catalog like this. Your own signals beat bought ones, because what happens on your website and in your inbox is more precise than any purchased dataset. Third-party intent is a good amplifier but rarely enough on its own. Providers infer topic interest from patterns across the web, and how reliable that is for your niche is something you have to check against your own deals. Breadth matters too: a buying group that's moving is worth more than one person who clicks a lot. Blog and newsletter activity, on the other hand, is almost worthless for scoring. It shows someone likes your content. It doesn't show they want to buy.
The most useful question for your signal catalog: which signals did the deals you won in the last twelve months have in common? And which of those did the lost ones have too? Whatever both had doesn't tell you anything.
How to weight it: multiply, don't add
The heart of any account score is how the three dimensions come together. Most models add them up, which sounds harmless but has a nasty side effect: one very high dimension compensates for a missing one. An account with fit 90, intent 90 and timing 5 averages out at 62, even though there's obviously no reason to call now.
So I combine them multiplicatively, usually with the geometric mean. Multiply the three values (each 0 to 100) and take the cube root. The result is back on a 0–100 scale, so it stays readable, but a weak dimension pulls the priority down noticeably. The same account now lands at 34; added up, it was 62.
Before any math, I check two things. First the knock-out criteria: competitor, customer with an open opportunity, partner, region outside your market. If any of those applies, fit is zero and the account isn't scored at all. Then come the minimums per dimension. If fit is below 40, the account goes no higher than the bottom band, however strong the intent. A small business that reads a lot is a nurture case.
Within the intent dimension, you do add up the weighted signals, because signals reinforce each other. Cap the sum at 100 so a single hyperactive account doesn't distort the whole ranking. For timing I use a baseline of 40 when no trigger is known. Zero would be wrong here, since not knowing a reason doesn't mean there isn't one.
Decay: every signal has a shelf life
A pricing page visit two days ago is a hot signal; the same visit two months ago is history. So every signal loses weight over time, and the simplest way to model that is a half-life. After seven days, a pricing page visit counts half as much, after 14 days a quarter. When a new signal arrives, the score climbs again.
The nice side effect is that the score drops on its own when an account cools off. Nobody has to reset old points by hand, and sales doesn't spend weeks staring at accounts at the top of the list that lost interest long ago.
Thresholds: when does a score become an action?
A score is only as good as the decision it triggers. I work with three bands plus a fast lane:
| Band | Rule | What happens |
|---|---|---|
| A – Activate | Priority 70 or higher, every dimension at least 40 | Buying-group research, account retargeting, outreach draft with human go |
| B – Warm up | Priority 50 to 69 | Account retargeting and nurture, no personal contact |
| C – Watch | Priority below 50 or fit below 40 | No effort, signals keep being collected |
| Fast lane | Demo request, direct reply, callback request | Straight to the owner, regardless of score |
Personal contact only pays off in the top right – and only once the timing is right.
People tend to forget the fast lane. Someone who requests a demo has stated their intent out loud, and running them through a scoring model first wastes time and, at worst, loses the deal.
Thresholds are capacity planning. Never put more accounts above the activation line than your team can properly handle in a week.
If 60 accounts land in band A every week but only two people work in sales, the threshold is too low. If two land there, it's probably too high, or you're missing signal sources.
How an agent computes and explains the score
In most companies, the data for all three dimensions already exists. It's just scattered across the CRM, analytics, your website's company identification, the intent provider, job postings and news. A person can pull that together for five accounts. For 40 or 400 accounts every week, nobody can, so in RevPrime® the Signal Agent takes it over.
- 01SignalWeb, CRM, intent, news
- 02Match & checkAccount, duplicates, knock-outs
- 03Score & reasoningFit × intent × timing, confidence
- GOHuman reviewOwner approves or rejects
- 05ActivationBuying group, channels, outreach
The Signal Agent computes and explains. Activation only happens after a human go.
The sequence is the same for every new signal:
- Match: the signal is assigned to an account via domain, company identification or a known CRM contact. Duplicates are merged.
- Check exclusions: customer with an open deal, competitor, partner, region outside your market? Then it stops here, with a note.
- Rate fit: firmographics and technographics against the criteria in “ICP & segments”.
- Compute intent and timing: weights from the signal catalog, decay by half-life, cap at 100, timing baseline.
- Set priority and band: geometric mean, check minimums, assign the band using the thresholds in “Priorities & KPIs”.
- Write the reasoning: the main drivers, what's missing, how solid the data is, which next step makes sense.
- Store and propose: score and reasoning go into the CRM, the proposal goes to the account owner.
Trust comes from step six. An Excel formula can do the math too. What the agent adds is language: why does this account fit? Which signal tipped the balance? What don't we know? A scoring sheet from the Signal Agent looks roughly like this:
Account: contract logistics, ~900 employees, DACH, 14 sites
Priority: 74 / 100 → band A (propose activation)
Overall confidence: medium

FIT 85 · confidence high
+ Contract logistics, 500–2,000 employees: core segment per ICP
+ Legacy TMS in use, migration proven per product truth
– No contact in the CRM yet

INTENT 71 · confidence medium
+25  Pricing page 3× in 6 days (last visit yesterday)
+18  Comparison page “TMS vs. spreadsheet dispatch”
+14  Two people active (operations, IT)
+9   Third-party topic “transport management” rising
+5   Contract logistics case study read
 0   Two newsletter clicks (don't count)

TIMING 68 · confidence medium
+ New head of operations, started 7 weeks ago
+ Two dispatcher job ads mentioning a system change
? Contract term of current system unknown

WHY NOW: new leadership plus a system topic in the job ads
plus broad, fresh intent on pricing and comparison.
OPEN: who owns the budget? Is a tender already running?

PROPOSAL (L1): start buying-group research, add account to
audience “TMS switch”, prepare draft to head of operations.
Waiting for go from: account owner
Confidence matters a lot here. Identifying companies by IP address gives you a probability, and third-party intent is a statistical model. A good agent says so openly and flags which parts of the score rest on shaky data. When confidence is low, I don't let the account slide into band A automatically. It goes to the review marked “please check”.
A score without reasoning is a claim. A score with reasoning is something you can work with.
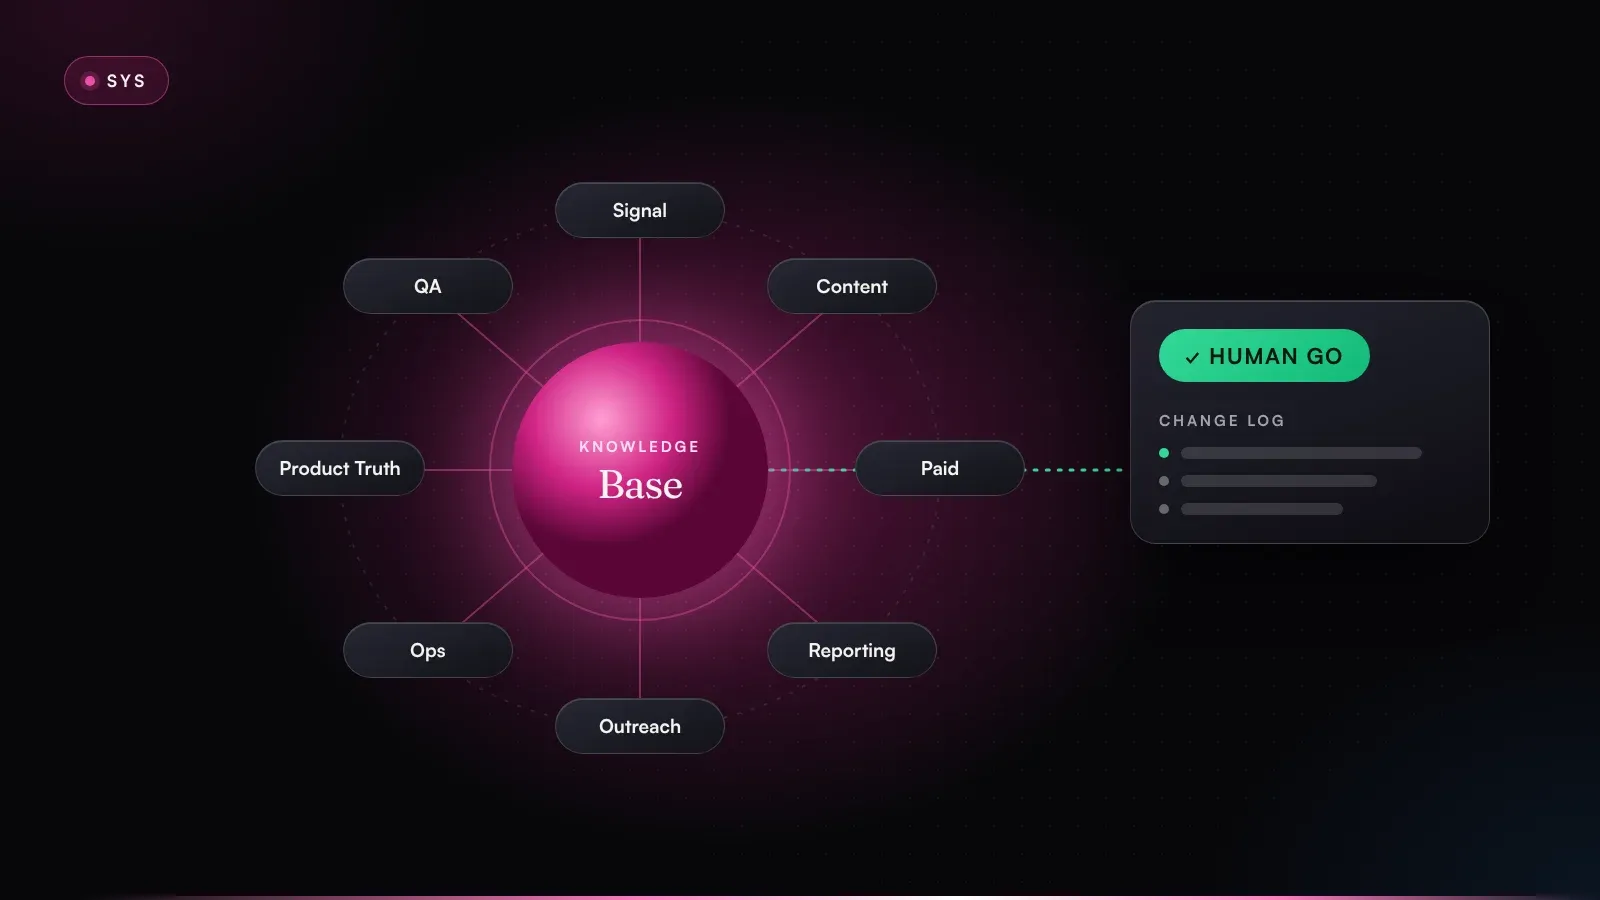
All the rules the agent applies (criteria, weights, half-lives, thresholds) live in the knowledge base. None of it sits in the agent's prompt. The reason is practical: when you change a threshold, the change reaches every agent the same day, and every change is traceable in the change log.
Worked example: a logistics software vendor with 40 target accounts
Say a vendor of transport management software sells to mid-sized freight forwarders and contract logistics providers in the DACH region. The team is small: a founder who handles sales, one account executive, one head of marketing. There are 40 companies on the target account list. The website identifies visiting companies, the CRM holds two years of deal history, and a third-party provider supplies topic intent.
The win/loss analysis of the last twelve months yields the fit criteria: 300 to 3,000 employees, at least five sites, dispatch run today in spreadsheets or a legacy system. Forwarders under 100 employees often became leads but almost never customers. Budget was usually the blocker.
After the first week in shadow mode, eleven of the 40 accounts show any signal at all. Five of them look like this (illustrative values):
| Account (example) | Fit | Intent | Timing | Additive (avg) | Priority (geom.) | Band |
|---|---|---|---|---|---|---|
| A: contract logistics, 900 staff | 85 | 71 | 68 | 75 | 74 | A |
| B: forwarder, 60 staff | 30 | 92 | 50 | 57 | 52 | C (fit below 40) |
| C: shipper with own fleet, 1,500 staff | 90 | 20 | 80 | 63 | 52 | B |
| D: contract logistics, 400 staff | 75 | 64 | 40 | 60 | 58 | B |
| E: 3PL provider, 2,000 staff | 80 | 76 | 70 | 75 | 75 | A |
For balanced profiles like A and E, both methods give almost the same result. It gets interesting with the outliers. Added up, the small forwarder B would score 57, almost level with D, carried entirely by an intent score of 92. It later turns out that a working student there is writing a thesis on dispatch software. The fit minimum drops the account into band C and keeps it out of both retargeting and the sales calendar. Account C, meanwhile, ranks ahead of D in the additive model and falls behind D once you multiply, because intent is missing.
Account C is the classic ABM profile: perfect fit, a new COO who started six weeks ago, but hardly any intent. A call would be premature. In band B, the buying group sees relevant LinkedIn content on modernizing dispatch after a leadership change, and as soon as someone visits the pricing page, the score climbs.
Accounts A and E land in band A, and the Signal Agent proposes activation for both. Then the weekly review does what makes a scoring model good: the account executive pushes back on E. She knows from a trade-show conversation that the provider signed with a competitor three months ago. The intent is there, but it comes from a team getting to grips with the new system and reading comparison pages because of it. Calling now would achieve nothing.
The agent records the no, with its reason, in the decision memory and proposes a new rule. If an account is known to have signed with a competitor in the last twelve months, timing is capped at 25 and a follow-up is set for the contract end. The head of marketing approves it, the rule goes into the “Playbooks & rules” module, and from then on it applies to every account.
For account A, the go triggers buying-group research with agents: who decides alongside the new head of operations, who owns the budget, who in IT will review the integration? The outreach draft references the leadership change and the job postings and leaves the website visit out. I cover how that becomes a message that doesn't sound like surveillance in From signal to message in 24 hours.
What agents do and what humans decide
Once agents are scoring, someone will ask who's in control. In my setups the split is fixed. Agents read, compute, explain and propose. Anything with external effect needs a human go, and only a human changes the rules themselves.
| Task | Who | Level |
|---|---|---|
| Read signals from CRM, website and intent sources | Signal Agent | L0 read |
| Write score, band and reasoning to the CRM | Signal Agent | L3 approved rule |
| Add band B accounts to retargeting audiences | Paid Media Agent | L2 write after go, later L3 |
| Propose activating a band A account | Signal Agent | L1 propose |
| Send an outreach draft, start a sequence | Outreach Routing Agent after the owner's go | L2 write after go |
| Change weights, half-lives, thresholds | Agent proposes, RevOps or revenue lead decides | Go plus change log |
| Define ICP and exclusion criteria | Revenue lead | Human decision |
The levels follow the permission ladder from L0 to L3. Many teams deliberately start with L0 and L1 only, so the agent scores and proposes but doesn't write anything to the CRM yet. Writing the score fields becomes an approved rule once sales has read the reasoning for a few weeks and trusts it.
The weekly score review
The most important human ritual is a short weekly review, 30 minutes with marketing, sales and RevOps, prepared by the Pipeline Reporting Agent. Three questions are on the agenda:
- Which band A accounts did sales accept, which did it reject, and why?
- Which accounts produced a meeting or opportunity without a high score? What did the model miss?
- Which rule change does the agent propose, and on what evidence?
A no is often worth more than a yes, because a rejected account with a reason teaches the rules something. Every decision goes into the decision memory with its reason, and over time the list of overrides becomes the best source for the next update.
Which metrics show your scoring works?
A scoring model is a hypothesis. The scores themselves can't tell you whether it holds; what happens afterwards can. These metrics belong in the weekly report:
| Metric | What it shows | Warning sign |
|---|---|---|
| Band A acceptance rate | Share of proposed accounts that sales works | Below half for several weeks |
| Meetings per band | Whether higher bands really produce more conversations | Band B converts as well as band A |
| Coverage of new opportunities | How many new deals were above the threshold beforehand | Lots of deals come “out of nowhere” |
| Override rate | How often humans correct the score | Zero (nobody's looking) or persistently high |
| Signal-to-action time | Hours from signal to proposal reaching the owner | More than one working day |
| Pipeline from band A | Opportunity value from activated accounts | Flat despite rising activation |
The check I find most telling is the band test. If the model works, the meeting rate rises noticeably from band C through B to A. If the curve is flat, your score isn't distinguishing anything, and either the weights are off or the signals are too thin.
Only run the test once enough accounts have accumulated per band. With 40 target accounts, that takes a few months, and until then the reasoning discussed in the review tells you more than any rate. I wouldn't celebrate an override rate of zero, by the way. Either the model is perfect or nobody's looking anymore, and I know which one I'd bet on.
Common account scoring mistakes
- Adding the dimensions up. One strong dimension masks a missing one, and sales gets accounts with no reason to call.
- No decay. The score only rises and keeps telling stories from three months ago.
- Treating third-party intent as truth. Topic signals are probabilities. They can amplify your own signals, but they can't replace them.
- Scoring people when accounts buy. Per-contact scoring misses the buying group and rewards the one person who reads everything.
- Gut-feel thresholds that are never calibrated. Thresholds have to match capacity and get adjusted against outcomes.
- A high score triggers contact automatically. Without a human go, you burn the very accounts that matter most.
- Black box. No reasoning, no trust; no trust, no usage. Plenty of scoring projects die of this without anyone noticing.
A high score triggers a proposal, not a contact. That one rule protects your best accounts from your fastest automations.
Your first four weeks
Your account scoring model won't be perfect on day one, and that's fine as long as it can learn. The plan below works for teams with 30 to 300 target accounts.
What you need first
The prerequisites are more modest than most people expect. You don't need a data science team or a new platform, because scores and reasoning land in the CRM you already use, such as HubSpot or Salesforce. What you do need:
- At least twelve months of won and lost opportunities in the CRM, ideally with source and first-touch date.
- Company identification on your website, so visits can be matched to accounts. It works at company level and is never complete.
- Firmographics and technographics (size, industry, sites, systems in use) from enrichment tools such as Clay or from your CRM.
- Third-party intent if you want it, as an amplifier on top.
- The knowledge base modules: “ICP & segments” for fit and exclusions, “Priorities & KPIs” for thresholds and SLAs, “Playbooks & rules” for the signal catalog and half-lives, and the “Decision memory” for every go and every no. “Buying center” joins once you want to score breadth.
On data protection: company identification delivers results at company level, but it processes IP addresses, which can themselves count as personal data. As soon as you enrich contacts or reach out, you need a legal basis, documented sources and clean opt-out processes. Clarify what that means for your channels and countries with your data protection officer before you start.
- Win/loss data for the last twelve months exported
- Fit criteria and knock-out criteria written down
- Company identification live on the website
- Signal catalog with starting weights and half-lives
- Thresholds matched to sales capacity
- Owner for the rulebook named (usually RevOps or the revenue lead)
- Weekly score review in the calendar
- Data protection questions settled with the responsible person
The plan, week by week
- Week 1Nail down fitWin/loss, ICP, knock-out list
- Week 2Signal catalogWeights, half-lives, L0
- Week 3Shadow modeScore, explain, don't act
- Week 4Thresholds & goActivate band A, start review
- From week 5CalibrateMonthly, with evidence and go
Clarify fit and signals first, calibrate in shadow mode, then activate with human go.
Week 1: Nail down fit. Export the deals of the last twelve months. Which industries, sizes and tech stacks do you win? Where do you keep losing? That gives you fit criteria and a knock-out list, and both go into the knowledge base, owned by the revenue lead.
Week 2: Build the signal catalog. Decide which signals count, with what weight and what half-life. Start from the table above and drop whatever you can't measure. Connect the sources read-only for now (L0): CRM, company identification, the intent provider if you have one.
Week 3: Shadow mode. The agent scores every account and writes the reasoning, but nobody acts on it yet. Sales looks at the top 10 and says where it's off. You'll never calibrate more cheaply.
Week 4: Thresholds and the first go. Set the thresholds so band A matches capacity. Start activation for band A with human go and launch the weekly review. From week 5, calibrate weights, half-lives and thresholds once a month, each time as a proposal with evidence, a go and a change log entry.
To see how scoring fits into the full loop of detecting, researching, mapping the buying group and reaching out, have a look at the intent-based activation use case with RevPrime®. If you want to know where your current scoring gets stuck, we can go through it together in a free 30-minute diagnosis call.
Frequently asked questions
What is an account scoring model?
An account scoring model rates how likely a company is to buy soon by combining signals from everyone at that company. Good models keep three dimensions apart: fit (does the account match your ICP?), intent (is it engaging with your topic right now?) and timing (is there a concrete trigger?). The resulting priority decides whether an account is activated, warmed up or simply watched.
What is the difference between lead scoring and account scoring?
Lead scoring rates individual people, usually by adding up points for activities. Account scoring looks at the whole company and merges signals from everyone in the buying group, which tells you more in high-value B2B deals where several people decide together.
Do I need a third-party intent data provider for intent scoring?
Not to get started. Your strongest signals are usually your own: repeat visits to pricing and comparison pages, replies to messages, webinar attendance. Third-party intent is a useful amplifier later on, but I'd test it against your own won deals before giving it much weight.
How often should you update a scoring model?
Weekly at first, in a short review with marketing, sales and RevOps, and roughly once a month after that. The input is the accounts sales rejected and the deals the model missed. Every change to weights or thresholds should be justified, approved and documented.
Is intent scoring GDPR compliant?
That depends on your data sources and how you use them. Company identification targets companies, but it processes IP addresses, which can count as personal data. As soon as personal data is involved, you need a legal basis, documented sources and opt-out processes. Clarify the details for your channels and countries with your data protection officer before you start.
Can an AI agent fully automate account scoring?
Partly. An agent can collect signals, compute the score, explain it and propose a next step. Anything with external effect, such as a message or a sequence, should be approved by a human. The same goes for weights and thresholds: the agent proposes changes, and a human decides.

About the author
Mario Maier
AI-native revenue marketing engineer · founder of igromo
For more than 15 years I've worked at the intersection of marketing, sales and revenue operations, from early-stage setups to scale-ups with multi-stage sales cycles and large buying centers. Since 2019 I've measured my work on pipeline and revenue.
Where do you stand?
The agentic readiness check shows in 3 minutes how ready your marketing is for agents – and which gaps to close first.
Keep reading
All insightsINT18 min read
AI SDRs in B2B: why autonomous outreach bots fail – and what works instead
AI SDRs in B2B: why autonomous outreach bots break on buying committees, deliverability and law – and how signal-based outreach with a human go works.
INT16 min read
From signal to message in 24 hours: signal-based outreach done right
Signal-based outreach turns buying signals into relevant, approved messages within a day. See the six steps, a worked example and a four-week start plan.
SYS24 min read
AI agents for B2B marketing: the complete guide from first prompt to pipeline
AI agents for B2B marketing that move pipeline: definition, architecture, 8 core agents with workflows, what not to automate, KPIs and a 90-day plan.